Same Brain, Different Bill
· 3 min read

Coding benchmarks are mostly about which frontier model solves the most tasks. Now that tokens are no longer free, what it costs to solve them matters just as much. Between the model and the bill sits the harness, which decides what goes into each request and how many requests a task takes.
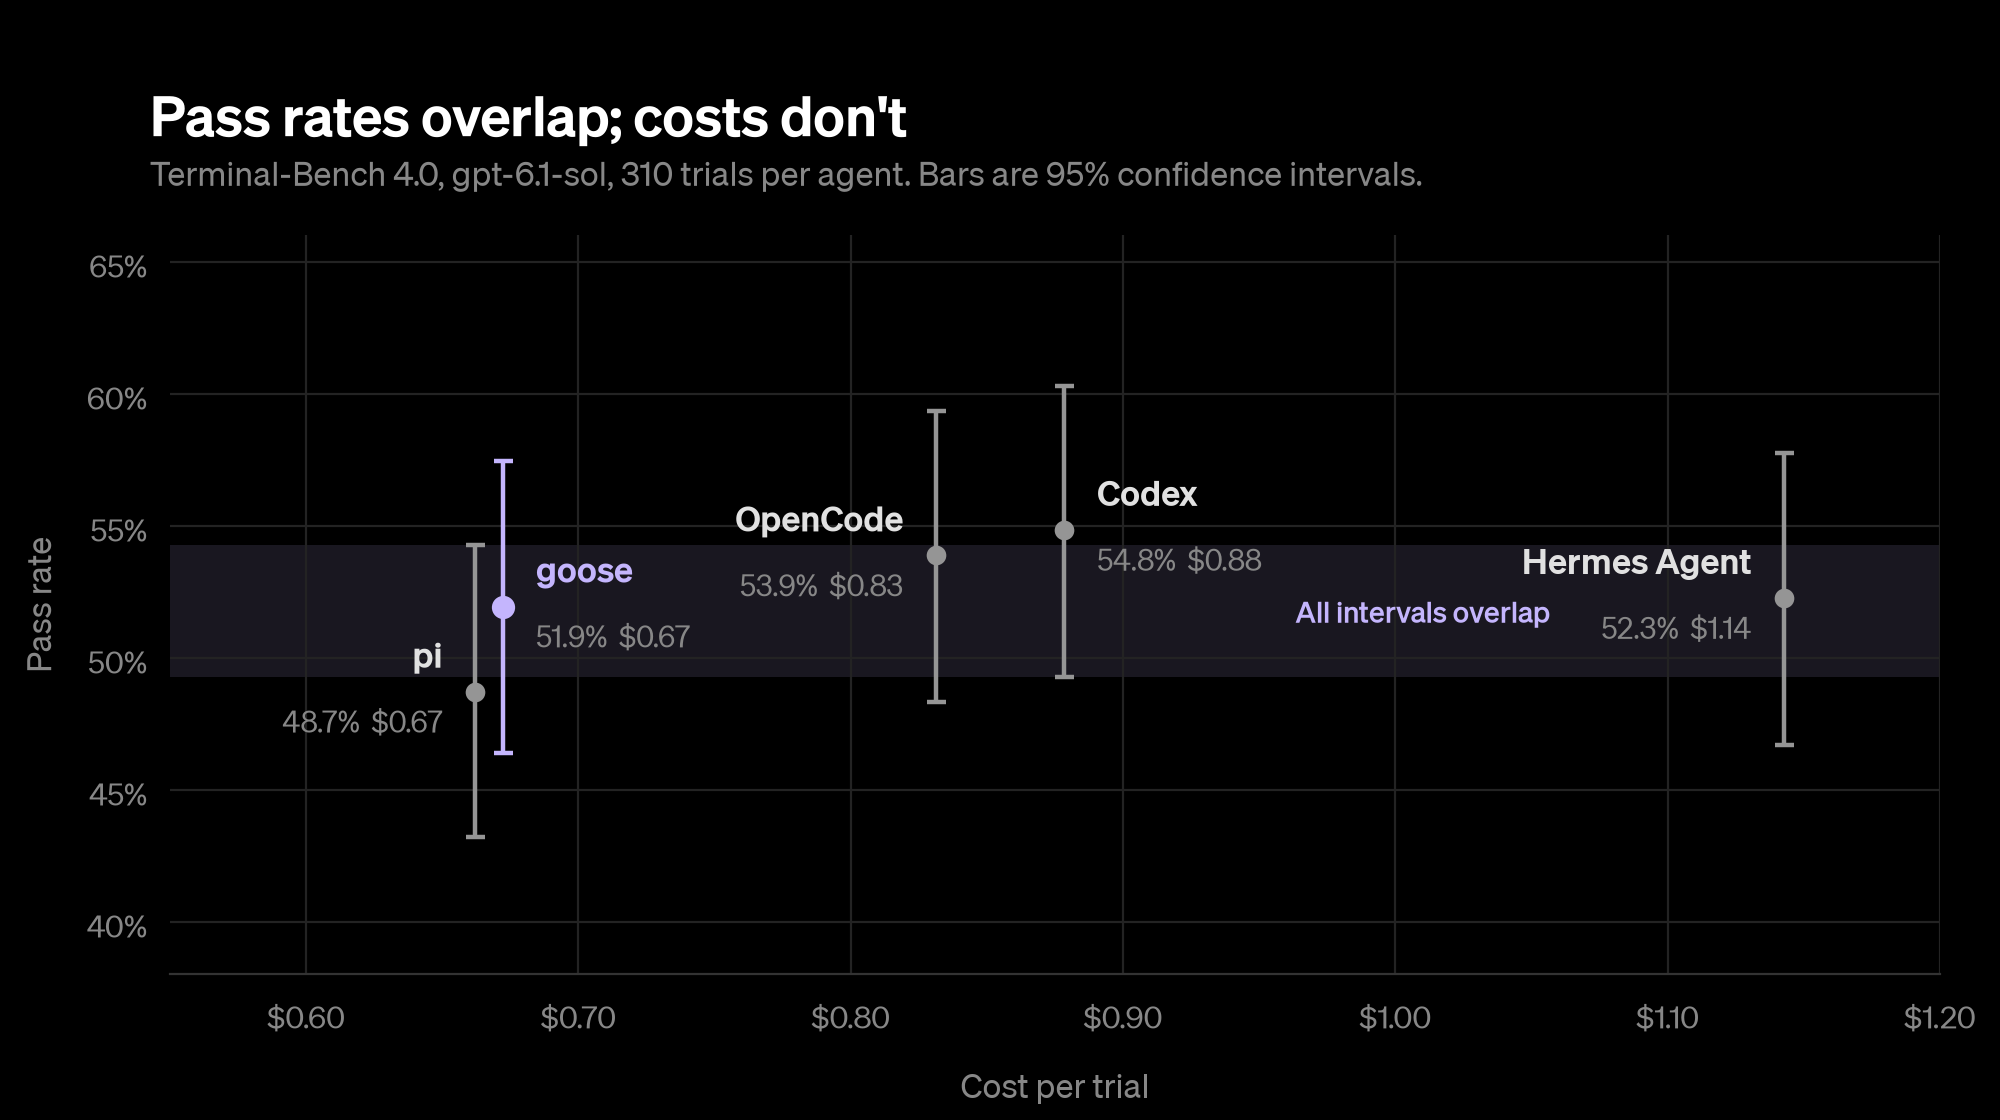
To see how much that layer matters, we gave five open harnesses (goose, Codex CLI, OpenCode, Hermes Agent and pi) the same model, gpt-6.1-sol at high reasoning effort, and the same Terminal-Bench 4 tasks. Each harness attempted every task five times, for 310 scored trials per harness.
Results
goose matched Codex CLI, OpenCode and Hermes Agent on pass rate. Its cost per task was 15 to 43% lower. pi tied goose on both.