Same Brain, Different Bill

Coding benchmarks are mostly about which frontier model solves the most tasks. Now that tokens are no longer free, what it costs to solve them matters just as much. Between the model and the bill sits the harness, which decides what goes into each request and how many requests a task takes.
To see how much that layer matters, we gave five open harnesses (goose, Codex CLI, OpenCode, Hermes Agent and pi) the same model, gpt-6.1-sol at high reasoning effort, and the same Terminal-Bench 4 tasks. Each harness attempted every task five times, for 310 scored trials per harness.
Results
goose matched Codex CLI, OpenCode and Hermes Agent on pass rate. Its cost per task was 15 to 43% lower. pi tied goose on both.
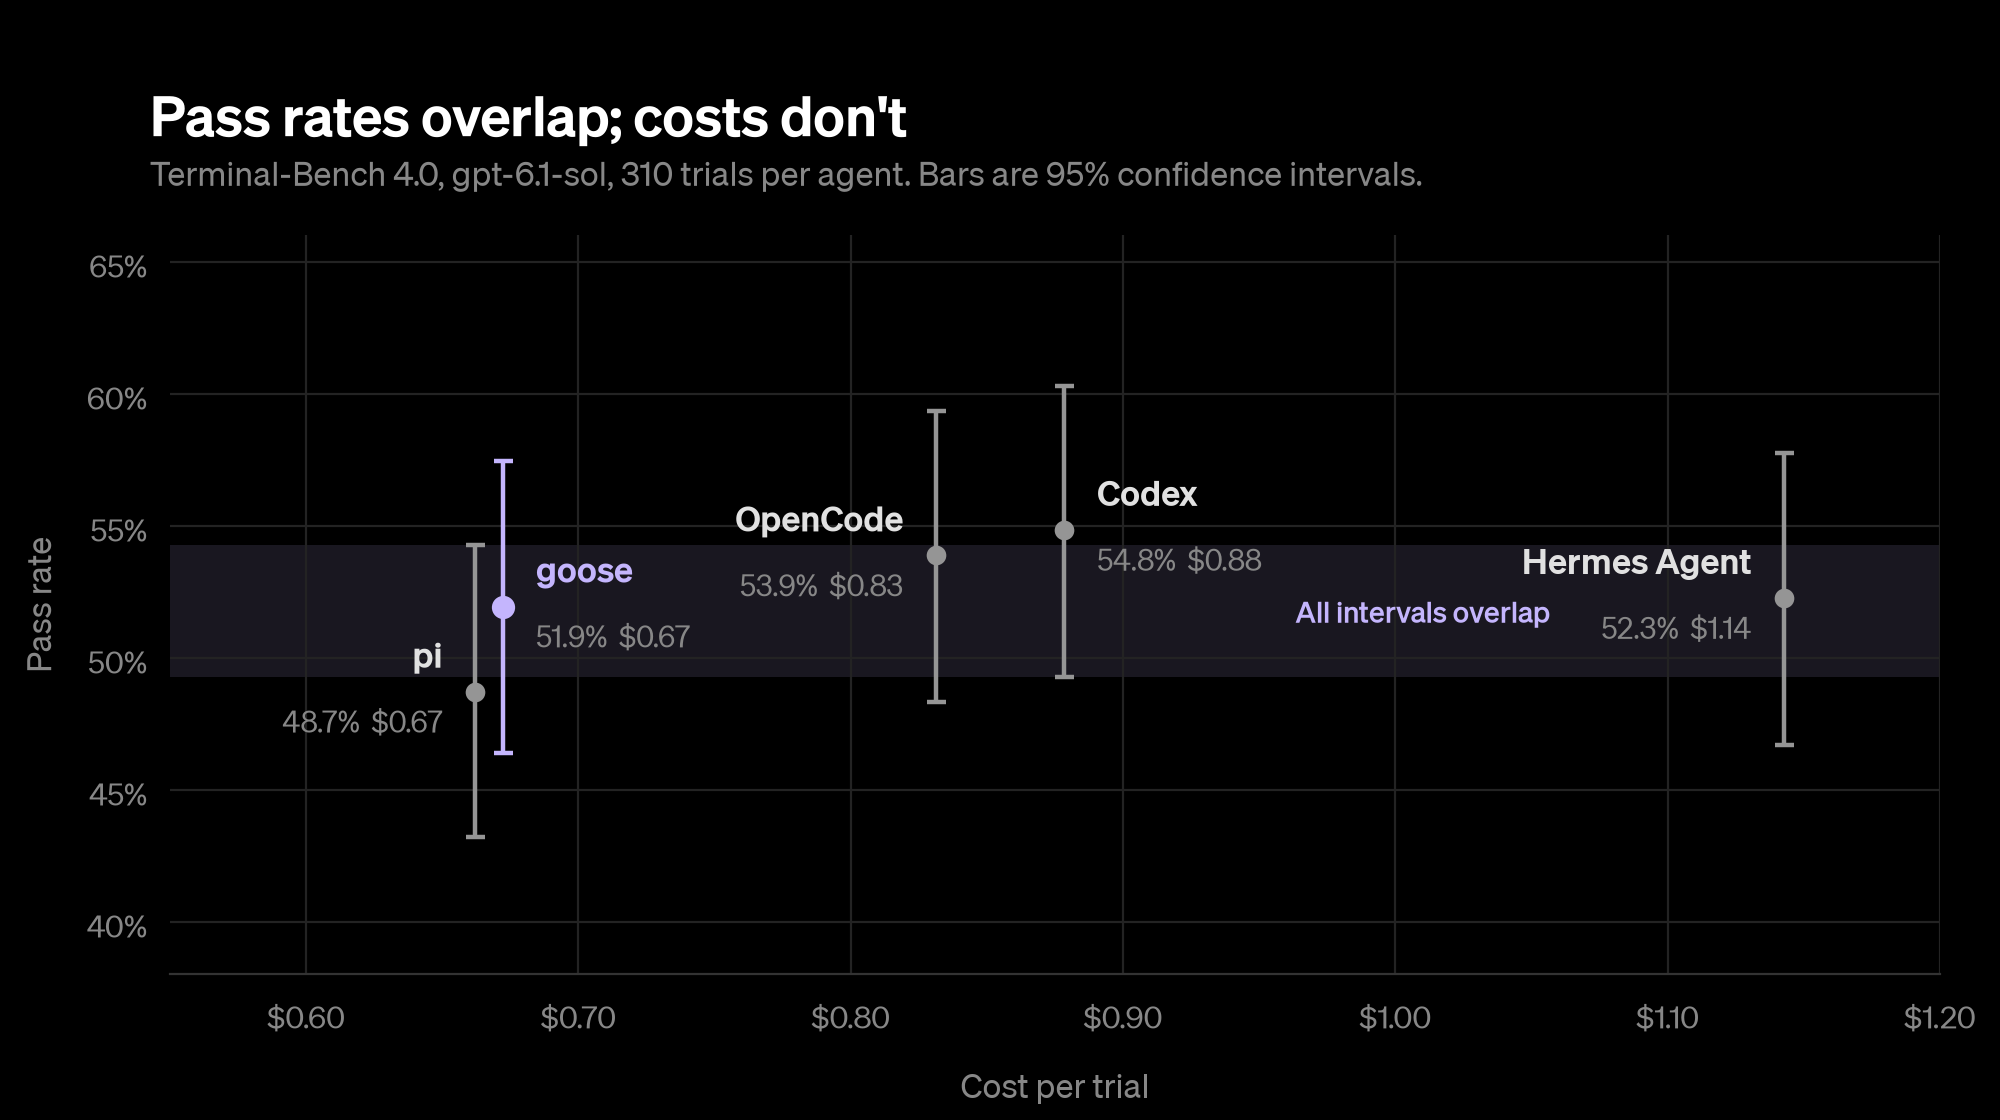
All five landed within about six points of each other on pass rate, and none differed from goose at 95% confidence. With the same model underneath, no harness solved noticeably more tasks.
Cost is a different story. Compared task by task, Codex cost 31% more than goose, OpenCode 18% more and Hermes Agent 75% more, all significant at 95%. pi cost about the same as goose.
| Harness | Pass rate | Cost per trial | Cost per solved task |
|---|---|---|---|
| goose | 51.9% | $0.67 | $1.29 |
| pi | 48.7% | $0.67 | $1.37 |
| OpenCode | 53.9% | $0.83 | $1.54 |
| Codex CLI | 54.8% | $0.88 | $1.60 |
| Hermes Agent | 52.3% | $1.14 | $2.19 |
How we ran it
- Tasks: Terminal-Bench 4.0, 62 of its 66 tasks. We excluded three that need a GPU and one whose required MCP server two of the adapters can't connect to.
- Harnesses: goose (main at
104ddde58), Codex CLI 0.160.1, OpenCode 1.18.35, Hermes Agent v0.21.6 and pi 1.0.4. Each ran through its built-in adapter in Harbor 0.24 with default prompts and limits, and reasoning effort set to high through the harness's own configuration. - Rounds: Five complete rounds of one trial per task per harness, with default task timeouts, on a single 16-core, 32 GB server.
- Cost: We didn't use any harness's own accounting. A proxy captured every request and response, and we priced the provider's reported token usage at list price.
- Reruns: Trials where the agent never started, such as a failed package install, were rerun. Trials where the agent started and then failed were scored as failures.